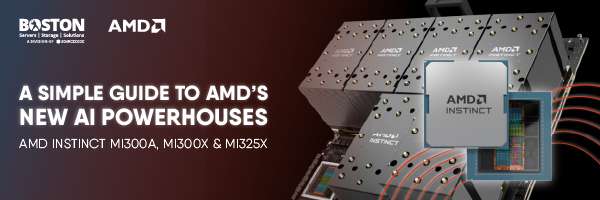
In today’s AI arms race, raw performance measured in TFLOPS or core counts alone is no longer enough. Increasingly what customers are looking for is scalability, memory density and operational efficiency. Introducing the AMD Instinct™ MI300 Series delivering exactly that, combining advanced 3D chiplet architecture with massive HBM capacity to unlock next-generation AI and HPC deployments.
Here’s how the portfolio aligns to modern enterprise and AI factory requirements.
MI300A – Converged HPC & AI Acceleration
The MI300A combines Zen 4 CPU cores and CDNA3 GPU compute into a single unified memory pool.
The Business Case
- Eliminates CPU–GPU data bottlenecks.
- Accelerates time-to-production.
- Optimised for the largest exascale datasets.
Ideal for: Large scale weather modelling, digital twins, energy simulation and high-density AI/HPC environments where rack space can be at a premium
MI300X – Enterprise Generative AI Engine
Purpose-built for large language model (LLM) training and inference. The 192GB HBM3 capacity allows larger models to stay “on-chip”.
The Business Case
- Stops Model Splitting: Fits massive models (like Llama 3 70B) on fewer GPUs, reducing the performance penalty of spreading data across multiple accelerators.
- Reduces Server Sprawl: Higher memory per GPU means you need fewer physical servers to run the same workload, cutting power and cooling overhead.
- Lower Cost-per-Query: Optimised memory paths increase the number of tokens generated per second, directly improving the ROI of inference API services.
Ideal for: Enterprise AI platforms, 70B+ parameter LLMs, secure on-premises AI deployments where data privacy is non-negotiable
MI325X – Ultra-Scale AI Factory Accelerator
Equipped with 256GB HBM3E and 6.0 TB/s bandwidth, this is designed for the highest possible data throughput.
The Business Case
- Trillion-Parameter Ready: Enables a single 8-GPU system to run trillion-parameter models that previously required massive, multi-rack clusters.
- Longer Context Handling: Allows AI to “remember” and process much larger documents or datasets (extended context windows) without crashing or slowing down.
- Maximizes Rack Revenue: Delivers the highest compute density available, allowing providers to sell more “AI compute hours” from the same square footage
Ideal for: Hyperscale cloud providers, real-time reasoning platforms and high-density clusters where speed is the primary competitive advantage.
Snapshot Comparison
| MI300A | MI300X | MI325X | |
| Primary Focus | Converged HPC & AI | Enterprise GenAI | High-Throughput Inference |
| HBM Memory | 128GB HBM3 | 192GB HBM3 | 256GB HBM3E |
| Memory Bandwidth | 5.3 TB/s | 5.3 TB/s | 6.0 TB/s |
| Single-GPU Capacity | ~40B Param Models | ~75B Param Models | ~100B+ Param Models |
| Max Power (TDP) | 550W – 760W | 750W | 1000W |
The Bottom Line
The MI300 Series is built for AI transformation at scale—reducing architectural complexity, improving utilisation and delivering measurable ROI per rack.
Whether deploying secure enterprise AI or building hyperscale AI factories, the MI300 portfolio provides the performance density and memory scale required to power the next wave of intelligent infrastructure.
Here at Boston, we can offer testing of all these products via our unique Boston Labs facility enabling testing of your actual workloads to ensure you will get the best bang for your buck!