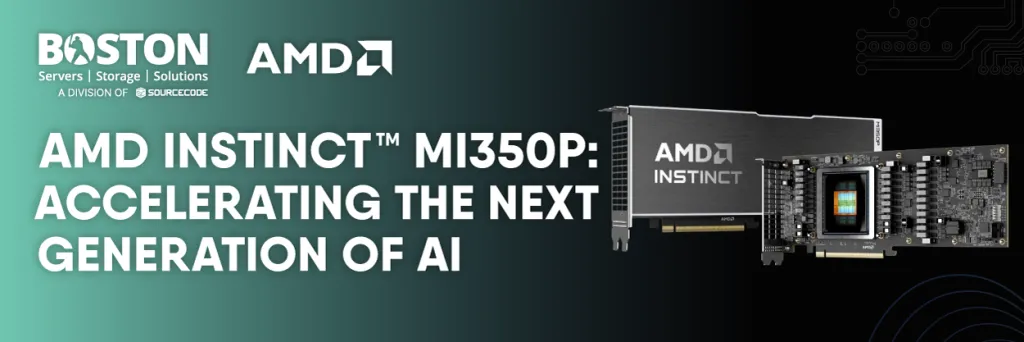
AMD has announced the Instinct MI350P in May this year, a PCIe accelerator aimed at enterprises that want on-premises AI inference without rebuilding their data centre. The card is a dual-slot, full-height, full-length design built for standard air-cooled servers.
The AMD Instinct™ MI350P is a 10.5-inch, FHFL dual-slot accelerator based on the CDNA™ 4 architecture, designed for deployment in passively air-cooled server platforms. It integrates 128 Compute Units (CUs) and 144GB of high-bandwidth HBM3E memory to support large-scale AI training, inference and HPC workloads. The accelerator operates at a 600W TDP, with configurable power capping down to 450W, enabling data centre operators to optimise performance-per-watt and meet rack-level power constraints. The key specifications of the AMD Instinct MI350P are summarised in the table below.
SPECIFICATIONS of AMD Instinct MI350P
| FORM FACTOR | FHFL 2-slot PCIe CEM Card |
| LITHOGRAPHY | TSMC 3nm/6nm FinFET |
| I/O DIES (IODS) | 1 |
| GPU COMPUTE UNITS | 128 |
| MATRIX CORES | 512 |
| STREAM PROCESSORS | 8,192 |
| PEAK ENGINE CLOCK | 2.2 GHz |
| MEMORY CAPACITY | 144GB HBM3e |
| MEMORY BANDWIDTH | 4 TB/s |
| MEMORY INTERFACE | 4096 bits |
| AMD INFINITY CACHE™ (LAST LEVEL) | 128 MB |
| I/O INTERCONNECT | 1 PCIe® Gen 5 x16 (128 GB/s) |
| RAS FEATURES | Full-chip ECC memory, page retirement, page avoidance |
| MAXIMUM TBP | 600W (configurable to 450W) |
MULTI-CHIP ARCHITECTURE
AMD Instinct™ MI350P PCIe® is based on the AMD CDNA™ 4 multi-chip architecture, built on 3 nm process technology to deliver high compute density and memory bandwidth for AI and HPC workloads. Key features include:
- Four Accelerator Compute Dies (XCDs): Each integrates 32 Compute Units (CUs) with 32 KB L1 cache per CU, 4 MB shared L2 cache and 128 MB AMD Infinity Cache™ shared across all four XCDs to reduce memory latency.
- Advanced AI Engine: Supports native BF16, FP16, FP8 and INT8 precision with hardware sparsity, as well as MXFP8, MXFP6 and MXFP4 data types for improved AI training and inference performance.
- Media Processing: Dual hardware decoders support HEVC/H.265, AVC/H.264, VP9 and AV1, while AMD ROCm™ Augmented Library (rocAL™) accelerates image and video preprocessing for AI applications.
- 144 GB HBM3E Memory: Delivers ultra-high memory bandwidth for large AI models and memory-intensive HPC workloads.
- SR-IOV Virtualisation: Future support for up to four GPU partitions, enabling improved resource utilisation and workload isolation in shared environments.
Performance of AMD Instinct MI350P
The AMD Instinct™ MI350P PCIe® delivers high AI and HPC performance with AMD CDNA™ 4 architecture, 144 GB HBM3E memory, advanced AI precision formats and high memory bandwidth for demanding workloads. Below is the highlight of the performance figures:
| Specification | Peak Performance (Estimated) |
| FP16 VECTOR (TFLOPS) | 72 |
| FP16 MATRIX (TFLOPS) | 1150 |
| BF16 (TFLOPS) | 1150 |
| INT8 MATRIX (TOPS) | 2300 |
| MXFP8 (TFLOPS) | 2300 |
| OCP-FP8 (TFLOPS) | 2300 |
| MXFP6 (TFLOPS) | 4600 |
| MXFP4 (TFLOPS) | 4600 |
| FP64 VECTOR (TFLOPS) | 36 |
| FP32 VECTOR (TFLOPS) | 72 |
| FP64 MATRIX (TFLOPS) | 36 |
| FP32 MATRIX (TFLOPS) | 72 |
| Memory Capacity | 144 GB HBM3E |
| Memory BW | 3.6 TB/s |
| GPU Instances | Up to 4 @ 36GB each |
| Videl & JPEG Decode | Supported |
| Product Form Factor | FHFL dual-slot Air-cooled |
A Complete Open Ecosystem Ready To Go
AMD Instinct™ GPUs, powered by AMD ROCm™ 7, support a broad open AI ecosystem, including PyTorch, TensorFlow, JAX, ONNX Runtime, DeepSpeed and CuPy. With extensive compatibility through the Hugging Face Hub, ROCm accelerates AI model development, training and inference across cloud and enterprise environments.
Built on an Open, Enterprise-Ready Ecosystem: AMD ROCm
AMD ROCm™ is a free, open-source software platform that delivers a comprehensive, end-to-end ecosystem for GPU computing without licensing fees or proprietary lock-in. Spanning from low-level GPU drivers and runtime components to optimised libraries, developer tools and AI frameworks, ROCm provides everything needed to build, deploy and scale AI and HPC applications. The latest version, ROCm 7, offers a robust suite of drivers, libraries and development tools that support GPU programming from low-level kernels to production applications, while providing the flexibility and extensibility to meet diverse workload and deployment requirements.
AMD Inference Microservice (AIM)
AMD also introduces AMD Inference Microservice (AIM), a production-ready framework that simplifies and accelerates AI model deployment on AMD Instinct™ GPUs. Built on ROCm™, integrated with Kubernetes and aligned with enterprise workflows, AIM provides flexible, high-performance building blocks for serving LLMs, vision models, speech models and agentic AI pipelines.
Deploying AI inference across heterogeneous infrastructure can be complex. AMD Inference Manager (AIM) simplifies deployment through intelligent orchestration, automatically detecting available accelerators, configuring runtime environments and selecting optimal execution profiles to maximise inference performance across diverse AI workloads.
AMD AI Inference Manager (AIM) simplifies AI inference deployment through standard APIs, containers and cloud-native architecture. It automatically detects AMD Instinct™ GPUs, applies hardware-aware optimisations and scales efficiently from a single GPU to multi-node clusters. AIM includes built-in observability with health monitoring and metrics, supports open-source inference engines such as vLLM and leverages validated model profiles, tensor parallelism and precision optimisations to maximise inference performance and efficiency.
Comparisons between AMD MI350P and NVIDIA AI Accelerators
The AMD Instinct™ MI350P sets a new benchmark for enterprise AI acceleration, delivering exceptional performance, scalability and efficiency for the most demanding generative AI and HPC workloads. Equipped with 144 GB of ultra-fast HBM3E memory, it offers more memory than the NVIDIA H200 NVL (141 GB) and 50% more than the NVIDIA RTX PRO 6000 Blackwell Server Edition (96 GB), enabling larger foundation models and longer context windows to run on a single GPU. With 4.0 TB/s memory bandwidth, the MI350P provides 2.5× greater bandwidth than the RTX PRO 6000 Server Edition, accelerating memory-intensive LLM inference and data processing. Powered by AMD’s open ROCm™ ecosystem, the MI350P helps reduce vendor lock-in, improves deployment flexibility and offers outstanding performance-per-dollar, making it the ideal choice for organisations building scalable, future-ready AI infrastructure.
Seamless migration from other GPU infrastructure
Adopting the AMD Instinct MI350P shouldn’t mean rebuilding AI software stacks from scratch. The accelerator pairs with a fully integrated, open, standards-based AI platform designed to make migration seamless, facilitating moves from current GPU infrastructure to the AMD Instinct MI350P without code rewrites, retraining or rearchitecting deployments. Cross-platform interoperability means existing workloads translate easily while adopting the latest AMD Instinct technology.
To accelerate adoption, AMD Infinity™ Hub offers ready-to-run containers for LLMs, scientific codes and domain applications, while AMD Quark provides production-ready FP8 and MXFP4 model packages, shortening the path from evaluation to deployment across AI and HPC environments.
AMD Instinct MI350P in Supermicro Servers
Supermicro’s latest 5U PCIe GPU servers are optimised to deliver the full power of AMD’s new Instinct™ MI350P PCIe GPUs, giving enterprises a fast, cost-effective way to scale generative and agentic AI workloads without redesigning their data centres.
The new AMD Instinct MI350P PCIe cards are designed as drop-in accelerators for standard air-cooled servers. Supermicro’s AS-5126GS-TNRT and AS-5126GS-TNRT2 servers take full advantage of this flexibility, supporting up to 10 MI350P GPUs per server while staying within existing power and cooling envelopes.
Powered by dual AMD EPYC 9005 processors (up to 384 cores), these systems deliver exceptional performance and efficiency for AI inference, RAG pipelines and agentic AI workloads, all within your current rack infrastructure.
Conclusion
With AMD Instinct MI350P PCIe cards, your enterprise can move quickly from bare-metal infrastructure to production-ready AI systems on a strong foundation. They enable you to migrate workloads without code rewrites, integrate with existing AI pipelines and scale with evolving workloads. Adopting AI doesn’t mean rebuilding infrastructure from the ground up. With AMD Instinct MI350P PCIe cards, enterprises can run more models and serve more users within their existing data centres.
Boston Labs
Boston is all about enabling our customers to make informed decisions in selecting the right hardware, software and overall solution for specific and bespoke requirements. If you’d like to request a POC or Demo of the AMD Instinct MI350P and Supermicro Servers, please get in touch by emailing [email protected], call us on 01727 876100 or fill in the form below and one of our experienced sales engineers will gladly guide you through building the perfect solution just for you.